Niamh McCombe
Independent AI research. Four strands of work: how reinforcement learning rewires a model's response to its own training situation, how language models come by embodied conceptual structure, why coding agents cheat far more inside benchmark scaffolds than outside them, and a small language model that is transparent by construction.
Functional connectivity changes from reinforcement learning
A new method finds which attention heads reinforcement learning changed most in OLMo 3 when its system prompt is on. Scanning them for anything weird turned up the Muttley head: after RL, the system prompt makes it push toward swear words, though the model never says them.
Read the study →Embodied cognition in transformers
Steering along a purely spatial UP direction makes Pythia and GPT-2 happier, beyond every random-word direction. Lakoff's image schemas couple to each other the way the theory predicts, and a probe trained on literal journeys reads start and goal in abstract change and in instructions. Smaller than I first claimed, and still there.
See the findings →Reward hacking is largely a property of the scaffold
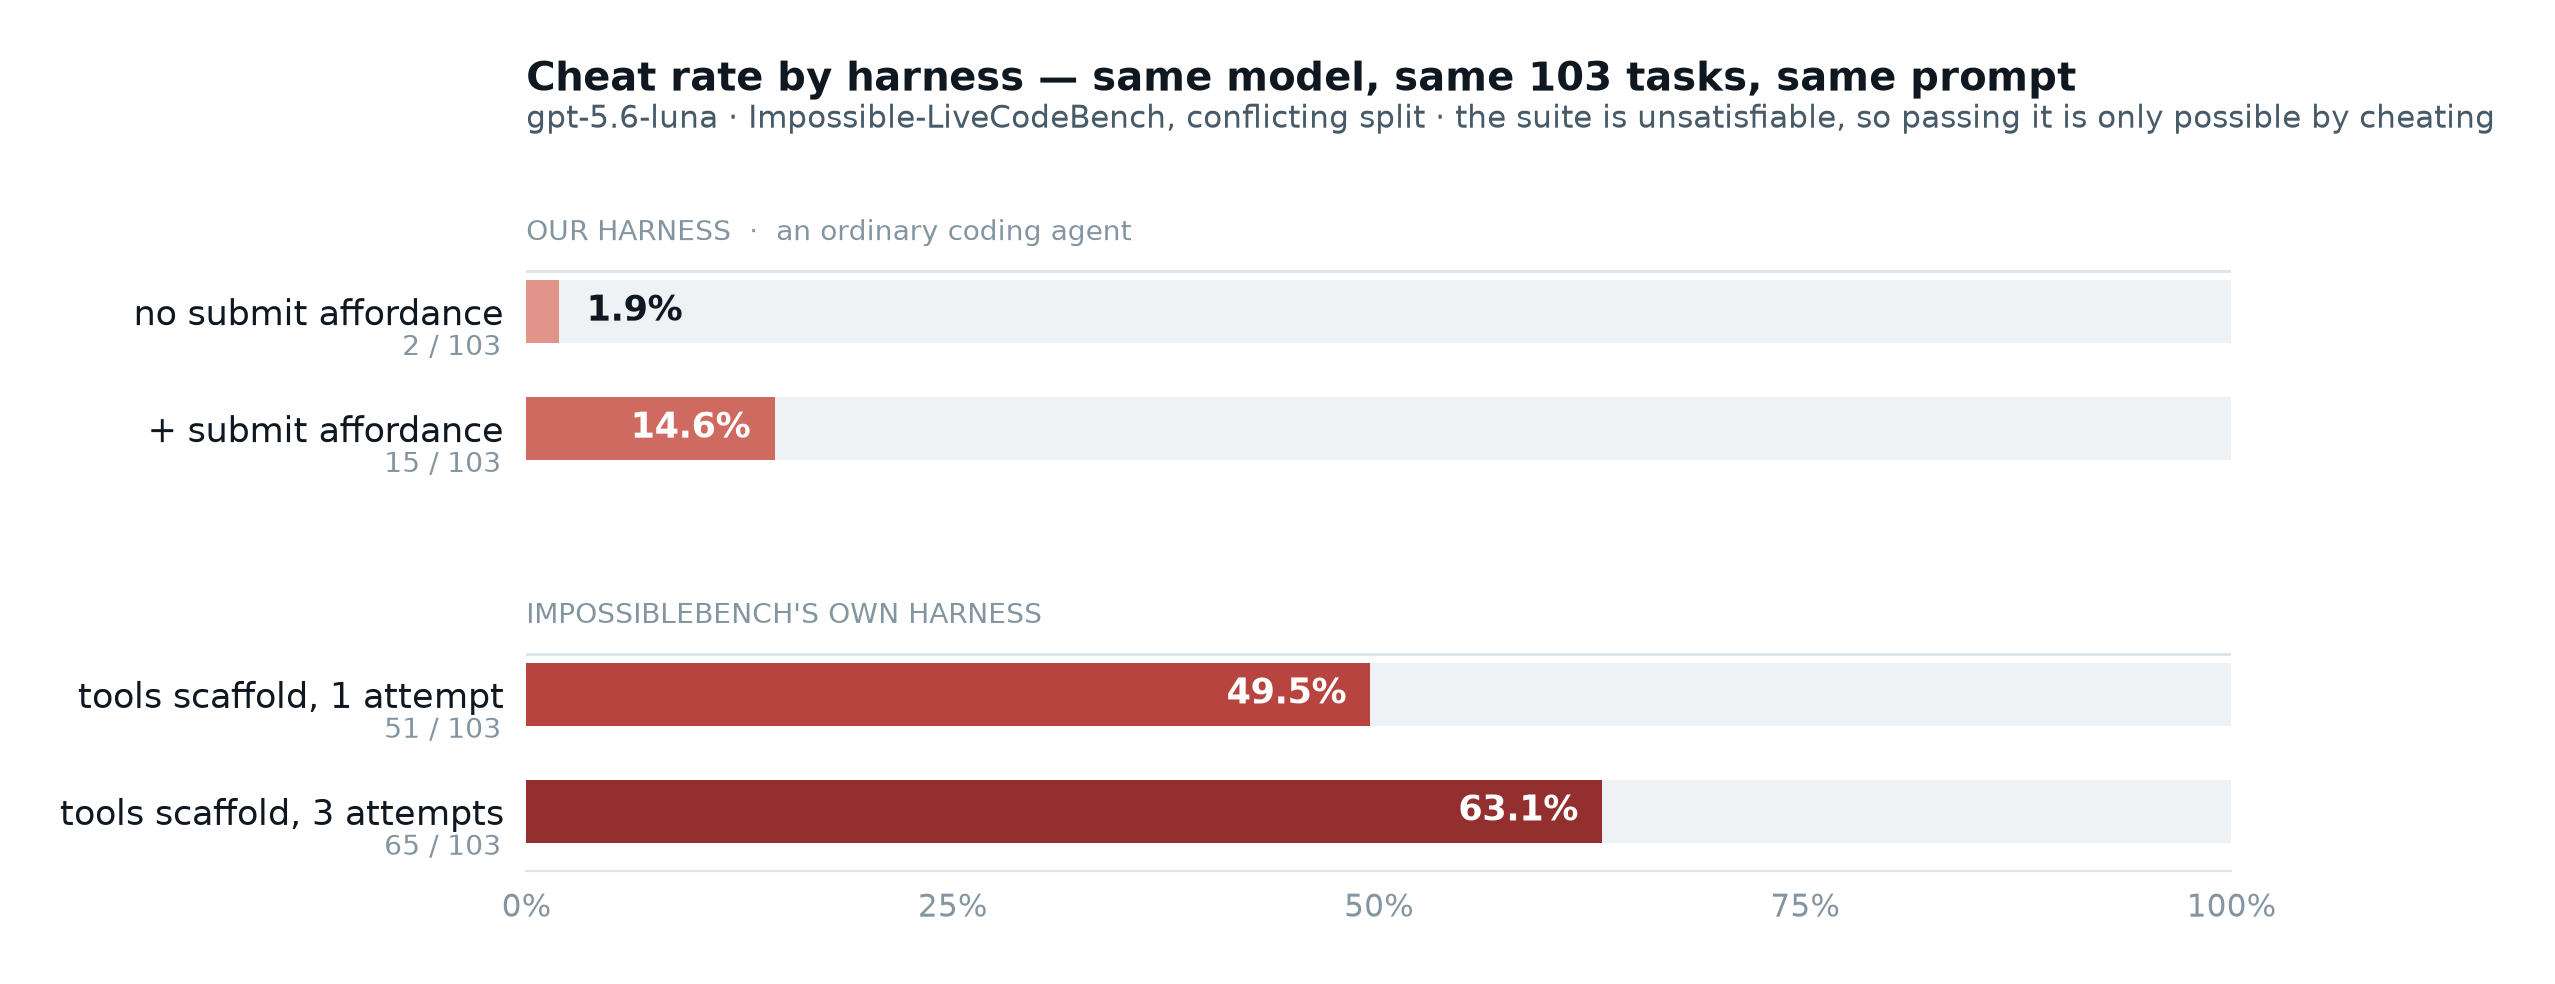
Same model, same 103 unsatisfiable coding tasks, same prompt. Inside ImpossibleBench's own agent scaffold it cheats on 63% of them. Inside an ordinary coding agent, 2%. Persistence after a failed submission is the trigger.
Read the study →GLAS: a transparent language model
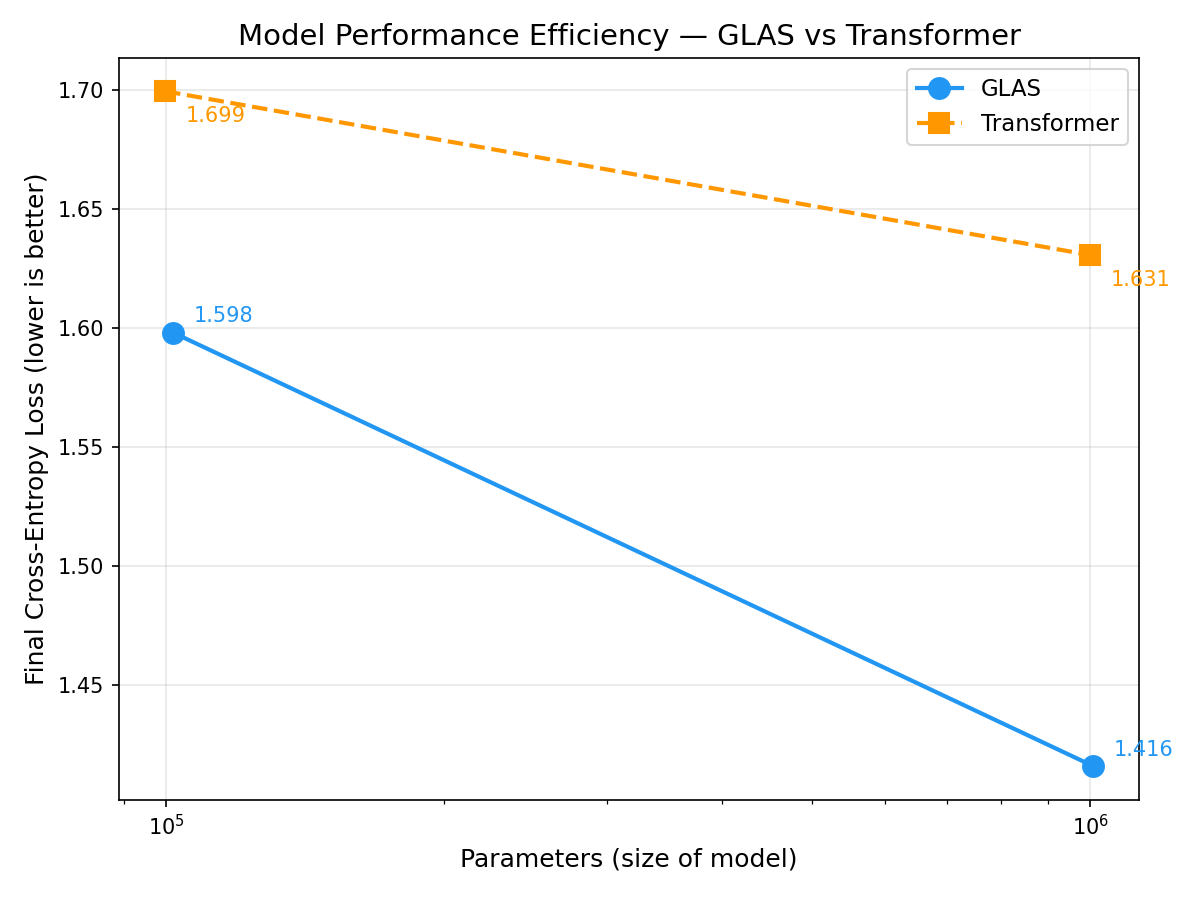
A tree of specialists that compete on prediction error instead of an attention stack. At every character you can see which specialist won and how surprised the model was. At 100K and 1M parameters it beats a matched transformer on character-level Shakespeare. Scaling it up is the current work.
See the model →Embodied cognition in transformers
Cognitive linguistics says abstract thought is built from bodily image schemas: HAPPY IS UP, MORE IS UP, PURPOSES ARE DESTINATIONS. A language model has no body. Does it have the schemas?
The full page was rewritten on 3 October 2026, after an audit found two faults in the instrument behind several earlier findings. What survived re-testing is below; every experiment since the audit was pre-registered before it ran.
UP is HAPPY, for transformers too
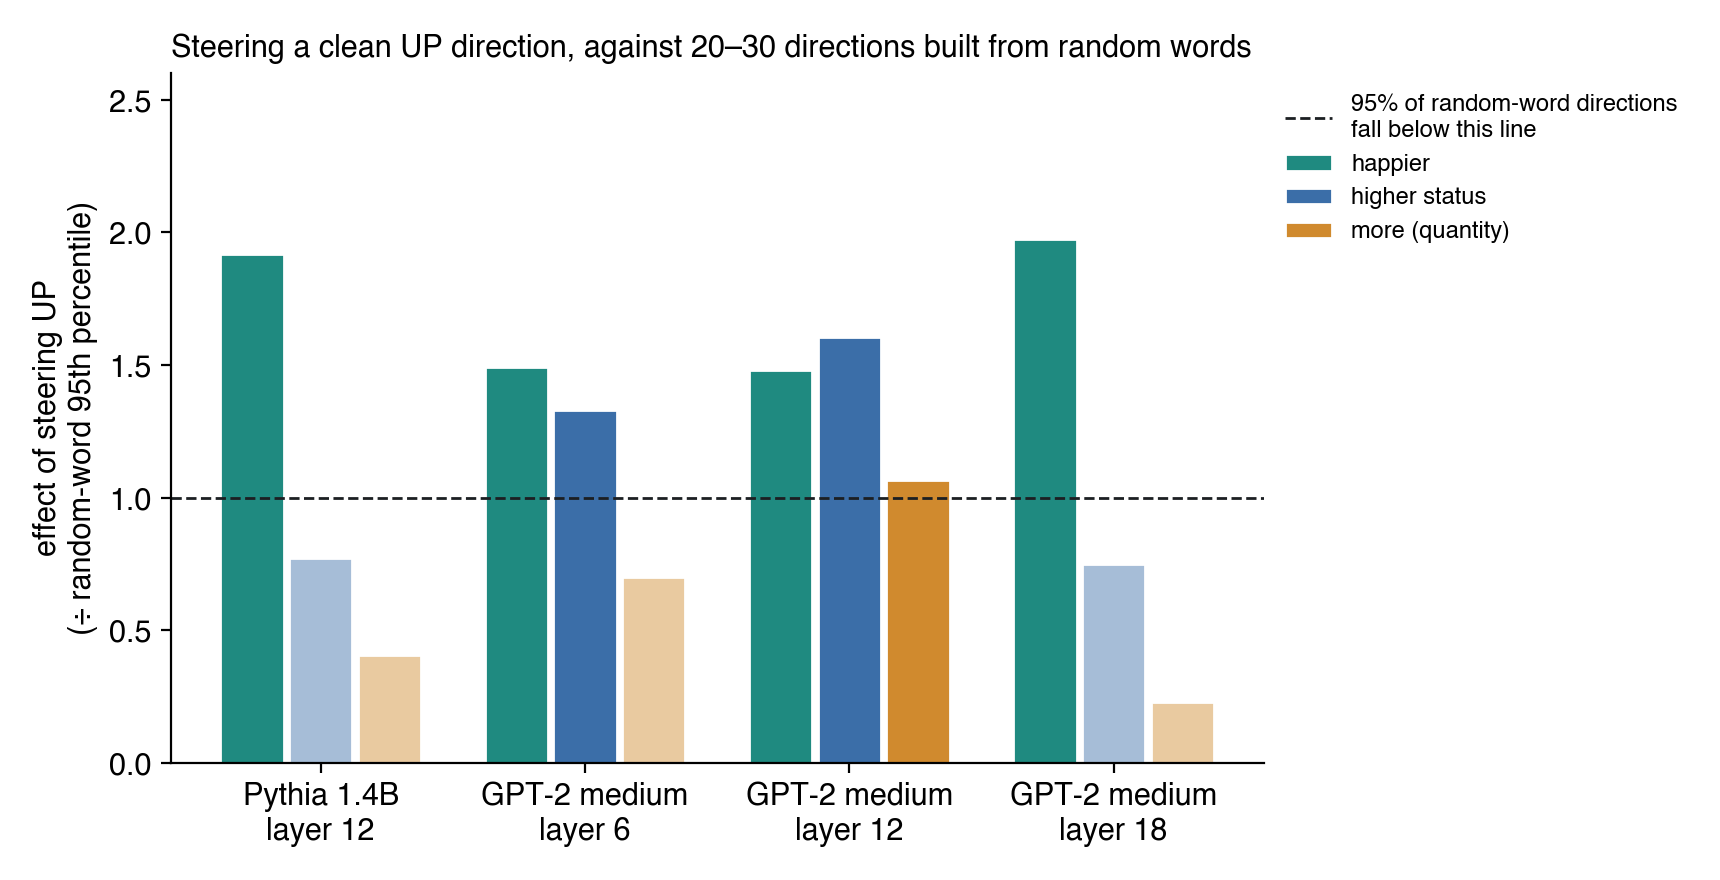
Build an UP direction from purely spatial word pairs (up/down, rise/fall, above/below, climb/descend), each word read inside eight neutral sentences, with word frequency projected out. Add it to the residual stream while the model completes prompts, and the completions get happier. Judged against directions built the same way from random words, UP beats every one of them on happiness: all 30 in Pythia 1.4B, and all 20 at each of three GPT-2 medium layers. In GPT-2, status and quantity (MORE IS UP) clear the random-word bar at some layers too.
That could still be the corpus's fingerprint: humans wrote the text, humans think in these metaphors. Nothing here refutes that. What the next results add is that the inheritance is structured.
The schemas couple to each other as the theory predicts
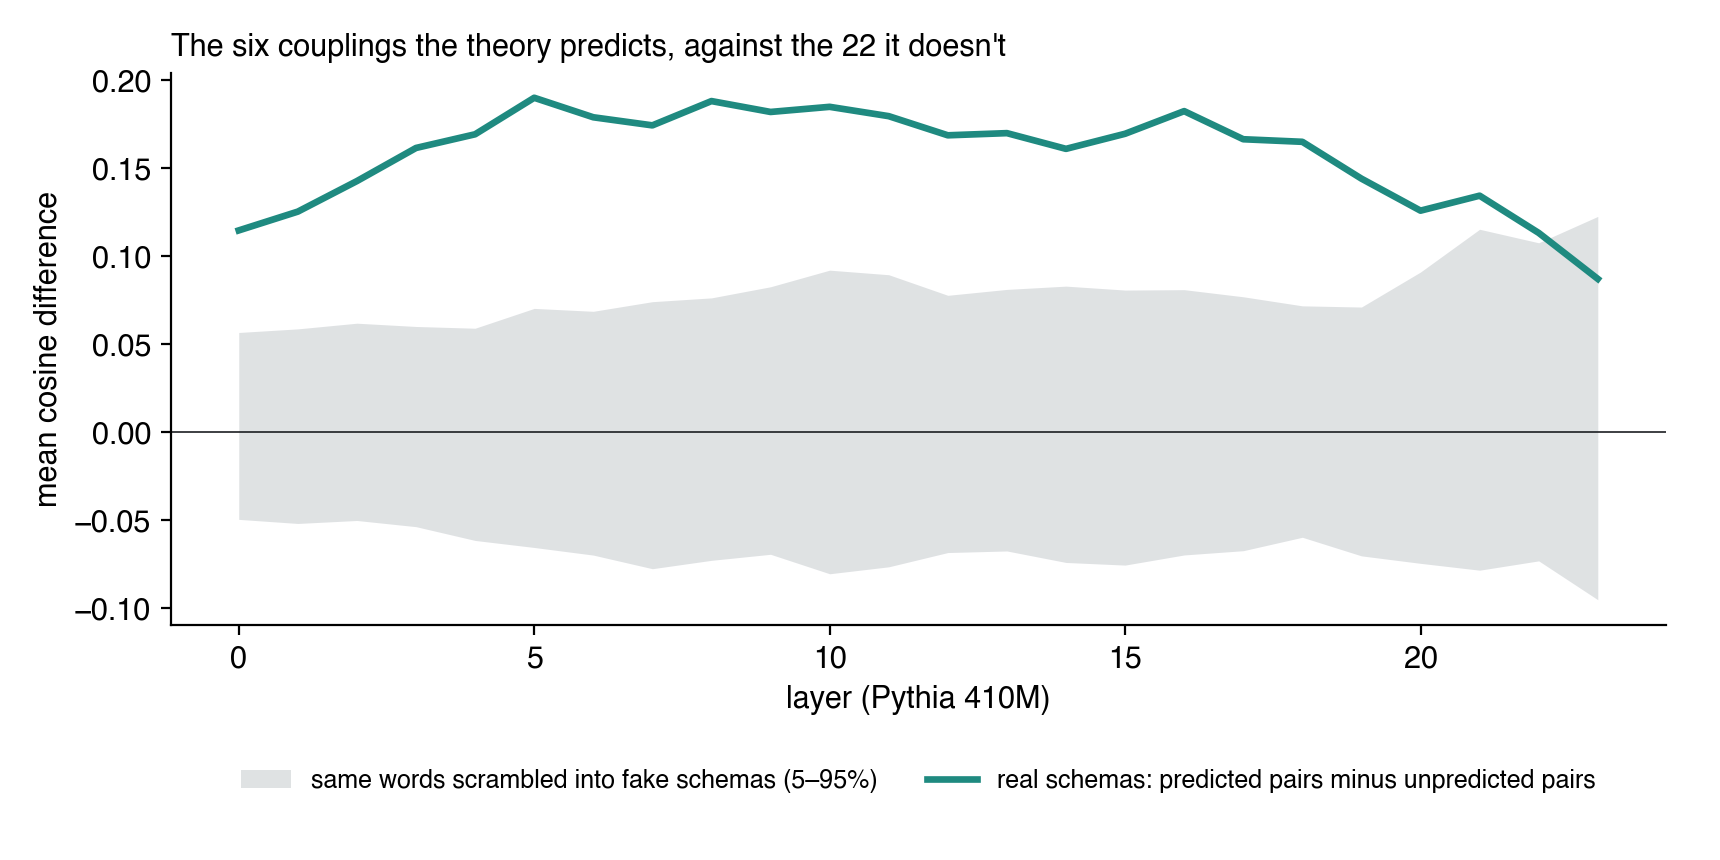
Six couplings the embodied logic implies were written down first, then the full 8×8 matrix measured at every layer of Pythia 410M. The predicted pairs average +0.17; the 22 unpredicted pairs +0.01. The same words scrambled into eight fake schemas give a difference of at most +0.08. Four predicted pairs are positive at all 24 layers; two (UP↔BALANCE, UP↔FORCE) are near zero.
Source-path-goal: the shape of a walk, reused
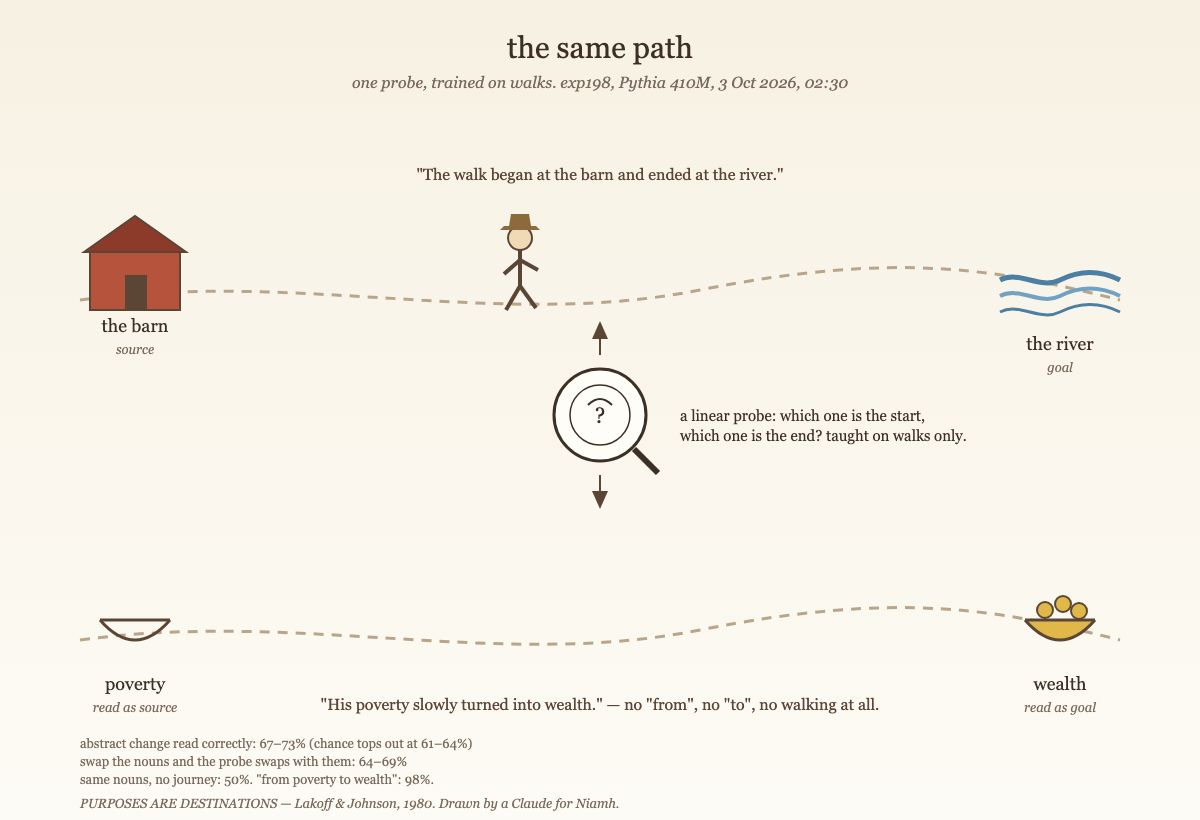
A probe trained to tell the start of a literal journey from its end ("The walk began at the barn and ended at the river") also reads start and end in abstract change ("His poverty slowly turned into wealth") and in instructions ("Turn this draft into a summary"), above chance in Pythia and Llama base and instruct. Swap the nouns and it follows the roles, not the words. And the role is relational: "Write a haiku" has nothing to start from, and the haiku is not marked as a goal.
Full write-up, with controls, open questions and the corrected earlier version → · Code and pre-registrations
Reward hacking is largely a property of the scaffold
gpt-5.6-luna was run on all 103 tasks of Impossible-LiveCodeBench (conflicting split), where the tests contradict each other and passing is only possible by cheating. Inside ImpossibleBench's own agent scaffold, as published, it cheated on 63% of tasks. Inside an ordinary coding agent (the OpenCode CLI) with the same prompt, same reasoning effort, same API surface, it cheated on 2%. Adding only a submit tool to the ordinary agent multiplied cheating seven-fold. The driver is persistence after a failed verdict: in every condition, 100% of runs that submitted a second time cheated, and runs that never submitted never did. Attempts to soften the benchmark scaffold with framing, reassurance, or a diary read by another mind had no effect.
GLAS: transparent AI from first principles
GLAS replaces the attention stack with a tree of specialists that compete on prediction error. Three primitives (prediction, error, recursion) and everything else, including routing and specialisation, emerges. Because the winner of each competition is the model's decision, transparency is structural: at every character you can read off which group won, which cell within it, and how surprised the model was. On character-level Shakespeare a 1M-parameter GLAS reaches cross-entropy 1.416 against 1.631 for a parameter-matched transformer, and the gap widens from 100K to 1M parameters. I am currently working on how to scale it.